Purpose
Translate the code from session 1 to R.
Read in data
-- Attaching packages --------------------------------------- tidyverse 1.3.1 --
v ggplot2 3.3.5     v purrr   0.3.4
v tibble  3.1.6     v dplyr   1.0.7
v tidyr   1.1.4     v stringr 1.4.0
v readr   2.1.1     v forcats 0.5.1
Warning: package 'tibble' was built under R version 4.1.2
Warning: package 'readr' was built under R version 4.1.2
-- Conflicts ------------------------------------------ tidyverse_conflicts() --
x dplyr::filter() masks stats::filter()
x dplyr::lag()    masks stats::lag()
theme_set(theme_light())

df <- readxl::read_excel(here::here("course-content/Class 1/Okun's Law.xlsx"), range = "A1:E45")

df <- df %>%
  janitor::clean_names()
EDA
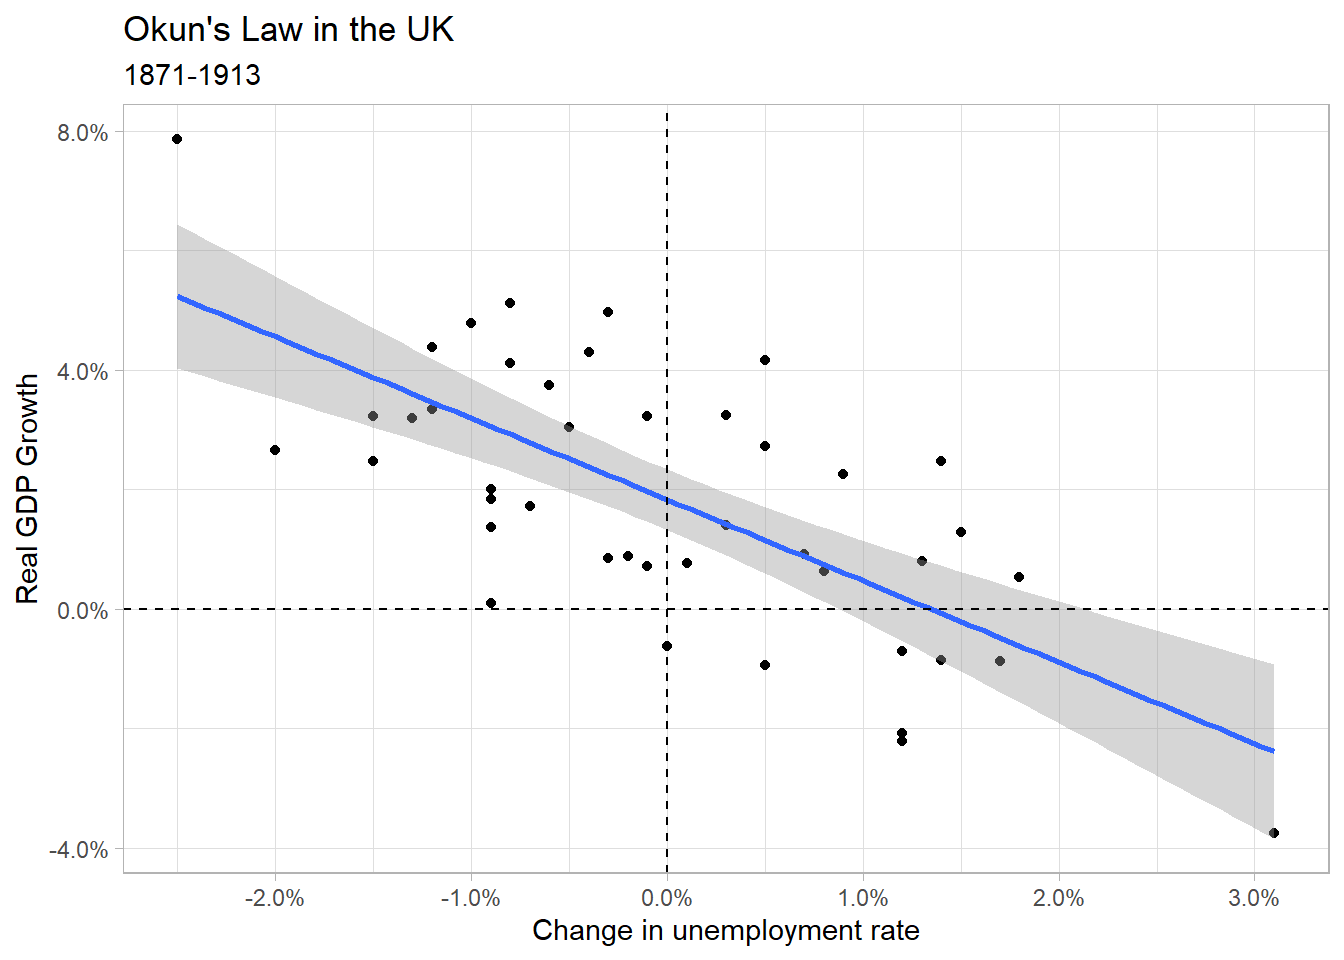
df %>%
  ggplot(aes(x = change_in_unemployment_rate_pp, y = real_gdp_growth_percent)) +
  geom_point() +
  geom_smooth(method = "lm") +
  scale_x_continuous(labels = scales::percent_format(scale = 1)) +
  scale_y_continuous(labels = scales::percent_format(scale = 1)) +
  geom_vline(xintercept = 0, lty = 2) +
  geom_hline(yintercept = 0, lty = 2) +
  labs(
    x = "Change in unemployment rate",
    y = "Real GDP Growth",
    title = "Okun's Law in the UK",
    subtitle = "1871-1913"
  )
`geom_smooth()` using formula 'y ~ x'
Warning: Removed 1 rows containing non-finite values (stat_smooth).
Warning: Removed 1 rows containing missing values (geom_point).
Regression
lm <- lm(real_gdp_growth_percent ~ change_in_unemployment_rate_pp, data = df)

lm %>%
  broom::tidy()
# A tibble: 2 x 5
  term                           estimate std.error statistic       p.value
  <chr>                             <dbl>     <dbl>     <dbl>         <dbl>
1 (Intercept)                        1.83     0.251      7.30 0.00000000631
2 change_in_unemployment_rate_pp    -1.36     0.218     -6.25 0.000000193
lm %>%
  gtsummary::tbl_regression(intercept = T)
| Characteristic |
Beta |
95% CI |
p-value |
| (Intercept) |
1.8 |
1.3, 2.3 |
<0.001 |
| change_in_unemployment_rate_pp |
-1.4 |
-1.8, -0.92 |
<0.001 |